Computational storage and eBPF: the break-even in bytes
Pushing a filter onto the drive or into the kernel sounds like free speed. It only pays below a keep-rate and above a scan size, and you can work out both with two numbers.
When does moving work into computational storage and eBPF pay off?#
Computational storage is a drive that runs your filter next to the flash, and like eBPF in the kernel it pays only when the filter discards most bytes before they cross the bus. So what is computational storage, in one line? In practice, it is compute placed on the storage side of the link between storage and compute.
The standard wording is brief. First, NVM Express, on its page updated 4 August 2026, calls its Computational Programs command set "a mechanism to execute programs on the device". Meanwhile, the eBPF Foundation says eBPF "can run sandboxed programs in a privileged context such as the operating system kernel". So the drive and the kernel are two places to run the same kind of small program.
Both places obey one rule. Because the link is the cost, the filter must throw away enough data that the link time saved beats the extra work done near the data. In short, it is a trade you can measure in milliseconds.
64 GB
Host path: every byte crosses
0.8 GB
Drive path: only kept rows cross
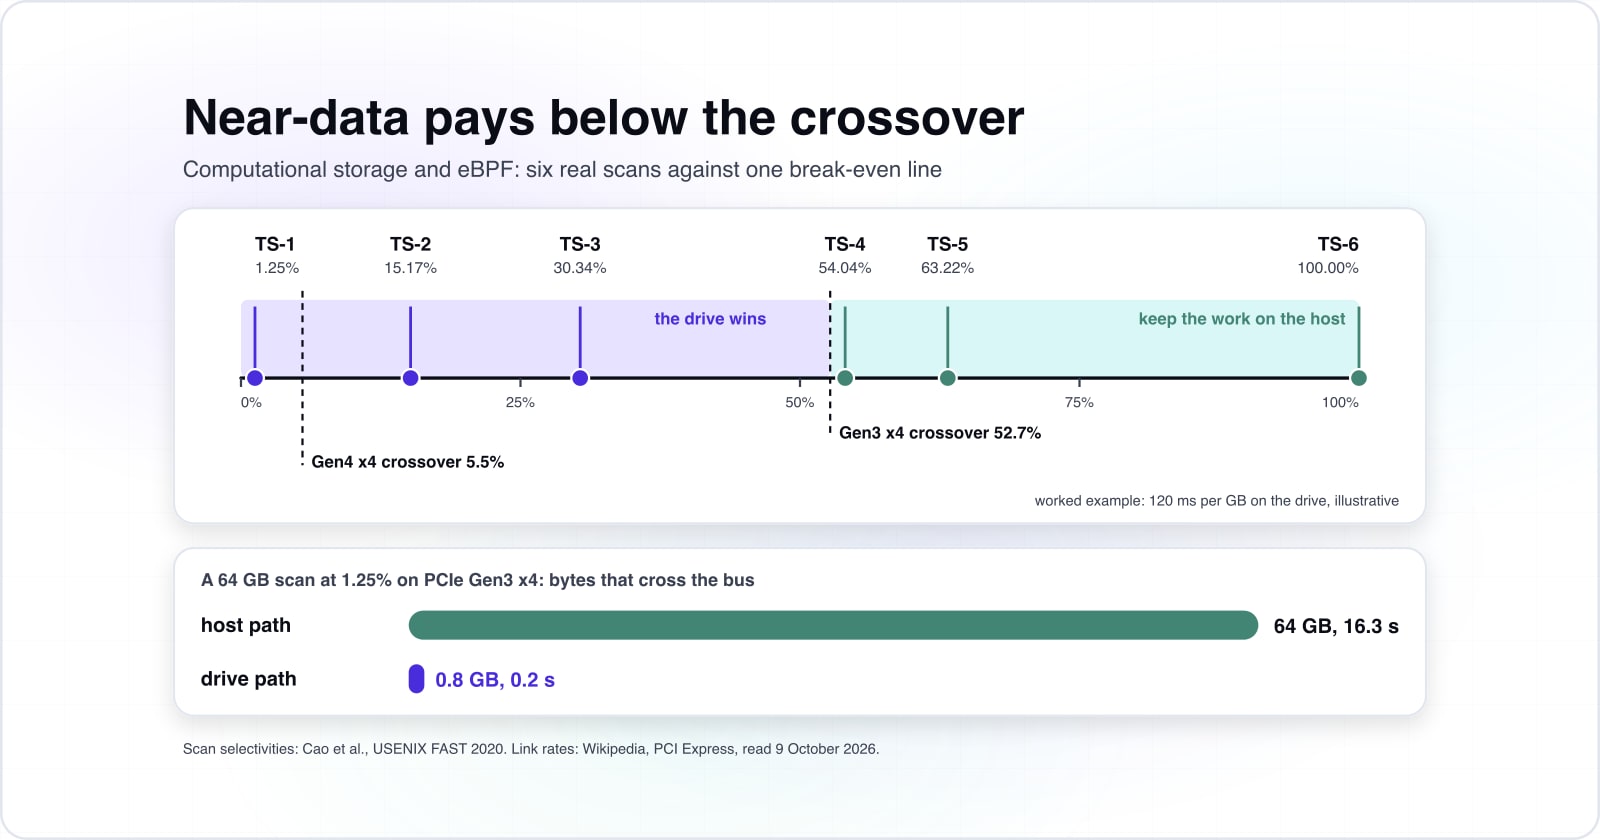
At the 1.25% selectivity of POLARDB scan TS-1, 0.8 GB crosses the bus instead of 64 GB. Arithmetic from Cao et al., USENIX FAST 2020; modelled, not measured.
| Option | gigabytes moved over the link at the 1.25% selectivity of POLARDB scan TS-1 |
|---|---|
| Host path: every byte crosses | 64 GB |
| Drive path: only kept rows cross | 0.8 GB |
Source: Cao et al., USENIX FAST 2020
What does a selective scan save on the bus?#
In a worked example of a 64 GB scan keeping 1.25% of rows, as in the USENIX FAST 2020 POLARDB paper, only 0.8 GB crosses the bus instead of 64 GB. That 1.25% is scan task TS-1 in the POLARDB paper by Cao et al. (FAST, February 2020). For that task, the authors report that a "CSD-based scan can almost eliminate the PCIe data transfer".
Next, turn the bytes into time. Wikipedia's PCI Express table (read 9 October 2026) lists 3.938 GB/s for Gen3 x4 and 7.877 GB/s for Gen4 x4. Then that works out to 253.9 ms and 127.0 ms per gigabyte. Therefore, at Wikipedia's Gen3 x4 rate the host path spends about 16.3 seconds moving 64 GB. Meanwhile, the drive path spends about 0.2 seconds moving 0.8 GB.
Show data table
| Item | Value |
|---|---|
| PCIe Gen3 x4 | 253.9 |
| PCIe Gen4 x4 | 127 |
Each gigabyte costs 253.9 ms on Gen3 x4 and 127.0 ms on Gen4 x4, so a faster link leaves less transfer time to save.
That is the number a platform lead can report upward. Bus time drops by a factor of eighty. Also, the host CPU never touches the rows the drive threw away.
What is a computational storage drive made of?#
A computational storage drive is an NVMe SSD with its own processor and memory, and the NVMe Computational Programs command set lets a host load and execute programs on it. In other words, a computational storage device is a normal SSD plus a place to run code and a place to keep its data.
NVM Express splits that into two command sets, both on pages updated 4 August 2026. First, Computational Programs covers "discovering pre-loaded programs, downloading programs and executing those programs". Second, Subsystem Local Memory (SLM) gives access to memory inside the drive, with commands to read, write and copy it.
The host flow follows. First, it loads data into SLM, runs a program with the Execute command, and reads back only the result. Also, the specification (revision 1.3, ratified 31 July 2026) makes activation a separate step. As a result, setup is paid once, before the first Execute.
What is eBPF, and why would a drive run it?#
eBPF is a small, verified instruction set for running sandboxed programs in the Linux kernel, and the NVMe Computational Programs specification lists it as a program type a drive can run. Also, the kernel documentation defines the instruction set. Then a verifier checks every program before it loads.
That verifier is why the format travels well, because it refuses any program it cannot prove safe. In particular, the kernel's BPF design notes, read 9 October 2026, cap how many instructions it explores: "Currently, that limit is set to 1 million." Because of that bound, a drive vendor gets a checkable program instead of arbitrary native code.
Speed depends on how the drive runs it. The NVMe specification of 31 July 2026 says activation "may involve transpiling an eBPF program" into native form. For example, the ZCSD prototype (arXiv, December 2021) filtered 64 million integers in a 256 MB zone. With just-in-time (JIT) compilation, that run came within 1% of its SPDK baseline. SPDK is the user-space driver kit the prototype uses to read the drive directly.
| Item | as printed (MB, kB, million integers) |
|---|---|
| zone size MB | 256 |
| page size kB | 4 |
| integers filtered, millions | 64 |
How do you compute the selectivity crossover?#
Near-data processing wins while selectivity stays below one minus the on-device compute time per gigabyte divided by the link transfer time per gigabyte. Here is where that comes from.
First, the host path moves every gigabyte, so it pays the full link time. Meanwhile, the drive path pays its own compute time on every gigabyte, then moves only the kept fraction. The drive wins while its compute time plus that kept share of link time stays under the full link time. As a result, solving for the kept fraction gives the crossover.
For example, say the drive's processor needs an illustrative 120 ms per gigabyte, so the Gen3 x4 crossover is one minus 120 over 253.9, or about 52.7%. However, at the Gen4 x4 rate it falls to about 5.5%. In practice, a faster link shrinks the time there is to save.
Bytes that cross the bus
- Traditional time
- 16.25 s
- Near-data time
- 7.88 s
- Crossover selectivity
- 52.7%
- Bytes kept off the bus
- 63.2 GB
At 1.25% selectivity, only 800 MB of the 64 GB scan needs to cross PCIe Gen3 x4. The 63.2 GB you keep off the bus outweighs the on-device compute penalty, so filtering on the drive returns the result sooner. You are below the crossover selectivity of 52.7%.
| Path | Bytes across bus | Transfer | On-device compute | Total time |
|---|---|---|---|---|
| Traditional (data to compute) | 64 GB | 16.25 s | 0 ms | 16.25 s |
| Near-data (compute to data) | 800 MB | 203 ms | 7.68 s | 7.88 s |
An illustrative planning model, not a benchmark. It assumes the traditional path moves every scanned byte across the bus, that the near-data path moves only the qualifying share plus an on-device compute penalty over the full scan, and that transfer cost is one over the published bus bandwidth. Real numbers move with your controller, compression, predicate cost, and driver, so use the crossover to find your regime, then measure your own workload before you commit.
Then place six real scans against that line. Cao et al. (FAST, February 2020) list selectivities of 1.25%, 15.17%, 30.34%, 54.04%, 63.22% and 100.00%. Against the Gen3 line, therefore, the first three favour the drive and the last three do not.
Show data table
| Item | Value |
|---|---|
| TS-1 | 1.25 |
| TS-2 | 15.17 |
| TS-3 | 30.34 |
| TS-4 | 54.04 |
| TS-5 | 63.22 |
| TS-6 | 100 |
TS-1 to TS-3 sit below the 52.7% Gen3 x4 crossover and favour the drive; TS-4 to TS-6 sit above it.
Why does a fixed command floor set a minimum scan size?#
Delilah, an eBPF computational storage prototype presented at DaMoN in June 2023, showed a 15 ms execution floor, which equals 59.1 MB of PCIe Gen3 x4 transfer. The paper says execution latency has a "high floor of approximately 15 ms", whatever the size of the data read.
That floor is paid before any byte is saved. Therefore, a scan smaller than what the link moves in 15 ms cannot win on the drive, even if the filter keeps nothing. Also, a faster link raises the bar. At the Gen4 x4 rate in Wikipedia's table (read 9 October 2026), the same 15 ms covers 118.2 MB.
59.1 MB
PCIe Gen3 x4
118.2 MB
PCIe Gen4 x4
A scan below these sizes cannot win on the drive. The Delilah 15 ms floor (Hedam et al., DaMoN 2023) times the x4 rates in Wikipedia's PCI Express table, read 9 October 2026; modelled, not measured.
| Option | megabytes moved in 15 ms at each x4 rate |
|---|---|
| PCIe Gen3 x4 | 59.1 MB |
| PCIe Gen4 x4 | 118.2 MB |
Source: Hedam et al., DaMoN 2023
How does XDP apply the same rule to packets?#
XDP runs an eBPF program inside the network driver before the kernel builds its packet structures, so a dropped packet never reaches the stack and only survivors pay for it. XDP (eXpress Data Path) is the hook. Then the program returns a verdict for each packet.
The eBPF Docs page on the XDP program type lists those verdicts. XDP_DROP discards the packet, and the page warns that "since we drop the packet very early" tcpdump will not see it. XDP_PASS hands the packet to the normal stack. Also, the kernel's AF_XDP path can redirect frames to user space.
The logic matches the drive. For instance, a filter that keeps few packets saves the kernel nearly all its per-packet work. Since the program runs in the driver, the only cost is the check itself. For the request path above this layer, see what happens when you hit a URL.
Which specifications do you build from?#
Build from these pages in order: the NVMe Computational Programs specification, the Subsystem Local Memory command set, the kernel BPF instruction set and verifier, then the XDP program type.
- 1
Computational Programs
NVMe Computational Programs command set: program discovery, download and the Execute command.
- 2
Subsystem Local Memory
NVMe Subsystem Local Memory command set: where an on-drive program reads and writes its data.
- 3
Instruction set
BPF instruction set: the instructions a drive interprets or compiles.
- 4
Verifier
BPF verifier: what is rejected before a program loads.
- 5
XDP program type
XDP program type: the context struct and the return codes.
- NVMe Computational Programs command set
- NVMe Subsystem Local Memory command set
- BPF instruction set
- BPF verifier
- XDP program type
What is the smallest eBPF filter you can run today?#
The smallest near-data program you can run today is an XDP filter in C that bounds-checks the Ethernet header, drops UDP and passes everything else. Drive-side eBPF needs a computational storage drive. However, this filter runs on any recent Linux box.
// drop_udp.c
// Build:  clang -O2 -g -target bpf -c drop_udp.c -o drop_udp.o
// Attach: ip link set dev veth0 xdpgeneric obj drop_udp.o sec xdp
#include <linux/bpf.h>
#include <linux/if_ether.h>
#include <linux/ip.h>
#include <linux/in.h>
#include <bpf/bpf_helpers.h>
#include <bpf/bpf_endian.h>

SEC("xdp")
int drop_udp(struct xdp_md *ctx)
{
    void *data = (void *)(long)ctx->data;
    void *data_end = (void *)(long)ctx->data_end;
    struct ethhdr *eth = data;
    struct iphdr *iph = data + sizeof(*eth);

    /* The verifier refuses any read it cannot prove stays inside the packet. */
    if (data + sizeof(*eth) + sizeof(*iph) > data_end)
        return XDP_PASS;
    if (eth->h_proto != bpf_htons(ETH_P_IP))
        return XDP_PASS;
    if (iph->protocol == IPPROTO_UDP)
        return XDP_DROP;
    return XDP_PASS;
}

char LICENSE[] SEC("license") = "GPL";
Attach it to a test interface first, because it drops DNS along with every other UDP packet. Also, the bounds check is the part the verifier demands. It follows the pattern the verifier page shows for direct packet access.
When is near-data processing not a fit?#
Near-data processing is not a fit when the filter keeps most rows, when scans are smaller than the command floor, or when the work needs data from more than one drive.
| Case | Why the drive loses | Better tool |
|---|---|---|
| The filter keeps most rows | TS-5 keeps 63.22% and TS-6 keeps 100.00%, above the crossover in the worked example | Keep the work on the host CPU |
| Scans smaller than the command floor | Below the 59.1 MB a Gen3 x4 link moves during the Delilah floor, the drive cannot win | Batch small reads into one large scan, or keep them on the host |
| Joins across drives | A program on one drive works on data in its own NVM subsystem | Run the join on the host |
First, high selectivity. In the POLARDB paper (Cao et al., FAST, February 2020), TS-5 keeps 63.22% and TS-6 keeps 100.00%. Both sit above the crossover in the worked example. For scans like those, keep the work on the host CPU. Then look at the same I/O bottlenecks that push teams toward in-storage compute.
Second, small scans. Below the 59.1 MB that a Gen3 x4 link moves during the Delilah floor (DaMoN, June 2023), the drive cannot win. Instead, batch small reads into one large scan, or keep them on the host.
Third, joins across drives. A program on one drive works on data in its own NVM subsystem. So a join that needs rows from two drives belongs on the host. Finally, the verifier caps what you can safely push into the kernel path, and the ZCSD result above was measured with JIT compilation. So ask whether a drive compiles eBPF before you trust that speed.
Where should you go next?#
Measure your own scan selectivity and link speed first, then follow the kernel-path, CPU cache and MySQL scan posts for the layers around this one. First, count the rows a real query keeps. Then read your link generation and width, and run the crossover before you buy hardware.
For the layers underneath, read why data locality beats data movement at the cache layer and the low-level systems mechanics most software engineers never see. Also, if a scan pipeline needs building, there is custom software development. For a platform whose scans are bus-bound, there is enterprise software work. Otherwise, the NVMe and kernel pages above are enough to start on your own.