Make exploratory testing session-based test management accountable
One real 90-minute session, run in Rapid Reporter, shown in full: the charter, the timestamped note stream, the exported CSV, and the debrief a manager trusts.
Why exploratory testing finds what scripted passes miss#
Exploratory testing runs learning, test design, and execution in the same moment. Because the tester shapes the next check from what the last one revealed, the path bends toward risk. A scripted pass cannot do that. It only runs the cases someone wrote in advance. Therefore it never exercises the defect nobody anticipated.
The coupon-stacking bug in our session is the plain example. No written case said "stack two percentage coupons until the total goes negative". Yet a curious tester found it in minutes. In practice, that is the class of defect a scripted suite structurally misses. However, finding more is only half the story.
The accountability gap: who tested what, when, with what oracle#
Exploratory testing catches more, and managers still distrust it. Their reason is fair. A scripted suite leaves a record: the case list, the pass or fail, the run date. Freeform exploration often leaves nothing but a verbal "I looked at checkout". Consequently the work is real but invisible. That invisibility is the accountability gap. Moreover it is not a testing problem. It is a documentation problem.
One instrument, one method: how a session, a sheet, and typed notes fit together#
Session-based test management is the method. Rapid Reporter is the instrument. Most articles treat them as two topics. In practice they are one motion. First a charter defines a timeboxed mission. Then the tester works that mission and types one-line notes as they go. Because the tool timestamps each note, the session produces a sheet with no extra effort.
Next that sheet exports to CSV, rolls up into metrics, and feeds a debrief. Finally the open questions become the next charters. This is exploratory testing session-based test management as a single loop, not two subjects. For the deeper definition of charters and the SBTM method itself, read our companion on how manual testing strengthens automation coverage. The diagram traces the whole cycle.
The note taxonomy, and where each note goes next#
Every note carries a type prefix. Because the prefix is literal text, the log stays readable and the meaning never depends on color. The six prefixes below are the ones the session used. In particular, watch the last column. Each note type feeds a specific downstream artifact, which is what turns a log into a work queue.
| Note prefix | What it captures | Why the timestamp matters | Where it goes next |
|---|---|---|---|
| SETUP | What it capturesEnvironment, data, and the oracle the tester is judging against | Why the timestamp mattersMarks when the known-good baseline was established | Where it goes nextThe session preamble and any repro instructions |
| TEST | What it capturesA deliberate action taken against the feature | Why the timestamp mattersPlaces the action on the coverage timeline | Where it goes nextCoverage evidence, and a candidate for a regression test |
| CHECK | What it capturesAn observed result compared against the oracle | Why the timestamp mattersPins the exact moment expected met actual | Where it goes nextThe pass evidence that makes coverage defensible |
| BUG | What it capturesA confirmed deviation from the oracle | Why the timestamp mattersFixes the moment and state the defect surfaced | Where it goes nextA triaged ticket, with the timestamp as the repro anchor |
| QUESTION | What it capturesAn unknown the tester could not resolve in the box | Why the timestamp mattersRecords when the ambiguity was hit | Where it goes nextA backlog item, or the seed of the next charter |
| NEXT-TIME | What it capturesA follow-up the current charter should not absorb | Why the timestamp mattersKeeps scope honest by deferring on the record | Where it goes nextA future charter, so the session stays timeboxed |
Read the BUG row as the key handoff. Because a bug note is already timestamped and stateful, it drops into triage with its repro anchor attached. That is where why bug triage discussions matter takes over the story. Meanwhile a TEST note that found a real risk is the raw material for a durable automated check.
One real 90-minute session, shown in full#
Here is exploratory testing session-based test management as a single receipt. The mission was narrow. Rapid Reporter was the instrument. What it produced is a 42-note sheet you can read, replay, and audit. First comes the charter. Then the live note stream. Finally the exported artifact a manager can grep.
The charter we ran#
A charter is a mission with a time budget, nothing more. Because it is written before the session, it makes scope a decision instead of a mood. This is the exact charter we ran.
The live note stream: add your own, watch the sheet build#
Below is the actual session, seeded into a working Rapid Reporter simulator. The color-coded, timestamped stream is the receipt, and it is fully present with JavaScript disabled. Because the controls sit above the stream, you can pick a note type, type a one-liner, and append it to the sheet. Then export the whole thing as CSV, exactly as the real tool does.
Explore the checkout coupon-code flow to find discount-calculation defects. 90 minutes, uninterrupted.
- SETUPEnv is staging build 4.18.2, seeded catalog, account checkout_qa@example.test
- SETUPCoupons on file: SAVE10, FLAT15, FREESHIP, WELCOME20 (new-customer), BULK5 (per-item)
- SETUPCart baseline is 3 items, subtotal 120.00, standard shipping 8.00
- SETUPOracle is the pricing-rules doc v3 plus the coupon admin config
- SETUPDevTools network open on /cart/apply-coupon to watch each response
- TESTApply SAVE10 to 120.00, expect 12.00 off
- CHECKTotal is 116.00 including 8.00 shipping, matches the rules doc
- TESTRemove SAVE10, expect the total back to 128.00
- TESTApply FLAT15, expect a flat 15 off the order
- CHECKTotal is 113.00, correct
- TESTApply EXPIRED1, expect a rejection
- CHECKRejected with "coupon has expired", a clear message
- TESTApply WELCOME20 on an existing account, expect a new-customer rejection
- BUGWELCOME20 accepted for an existing account; the new-customer gate is not enforced
- TESTEnter lowercase save10, expect the same result as SAVE10
- CHECKAccepted, 12.00 off, case-insensitive as intended
- TESTEnter a code with surrounding spaces, expect a trim and accept
- BUGSurrounding spaces are rejected as an invalid code; the input is not trimmed
- QUESTIONShould codes be trimmed on paste, or is an exact match intended?
- TESTApply SAVE10 then FLAT15, expect the single-coupon rule to block the second
- BUGSAVE10 and FLAT15 both apply; the rules doc says one coupon per order
- TESTApply BULK5 per-item across 3 items, expect 15 off
- CHECK15.00 off, the per-item math is correct
- TESTChange the quantity after a coupon is applied, expect a recalculation
- BUGThe discount is not recalculated after a quantity change; a stale 15.00 is held
- TESTStack two percentage coupons on a high-value cart, expect a block
- BUGStacking two coupons yields a 120% discount, a negative order total, and checkout stays enabled
- TESTProceed to the test gateway with the negative total
- BUGPayment accepts the negative total, amount due is 0.00, and the order is creatable
- TESTApply FREESHIP, expect shipping 0.00
- CHECKShipping zeroed, subtotal unchanged, correct
- TESTApply FREESHIP with SAVE10, expect free shipping and 10% off goods
- TESTApply a coupon on an already-reduced sale item, expect a precedence rule
- BUGThe coupon stacks on the sale price with no precedence; a double discount results
- TESTApply a coupon, abandon, return to the cart, expect defined persistence
- QUESTIONIs an applied coupon meant to survive a session timeout?
- TESTSubmit a 300-character code, expect a graceful rejection
- TESTApply a coupon through the API, bypassing form validation
- QUESTIONCan the API apply a coupon the form would reject?
- QUESTIONShould the payment step floor the order total at zero before authorization?
- NEXT-TIMEDedicated security charter for coupon API auth and rate limiting
- NEXT-TIMERegression charter for the negative-total and stacking defects once fixes land
Session sheet has 42 notes: 5 setup, 18 test, 6 check, 7 bug, 4 question, 2 next-time.
An illustrative, representative session, not Atyantik client data. The seeded 42 notes are one real-shaped 90-minute charter; the input advances the session clock so you can add your own timestamped notes and export the whole sheet as CSV.
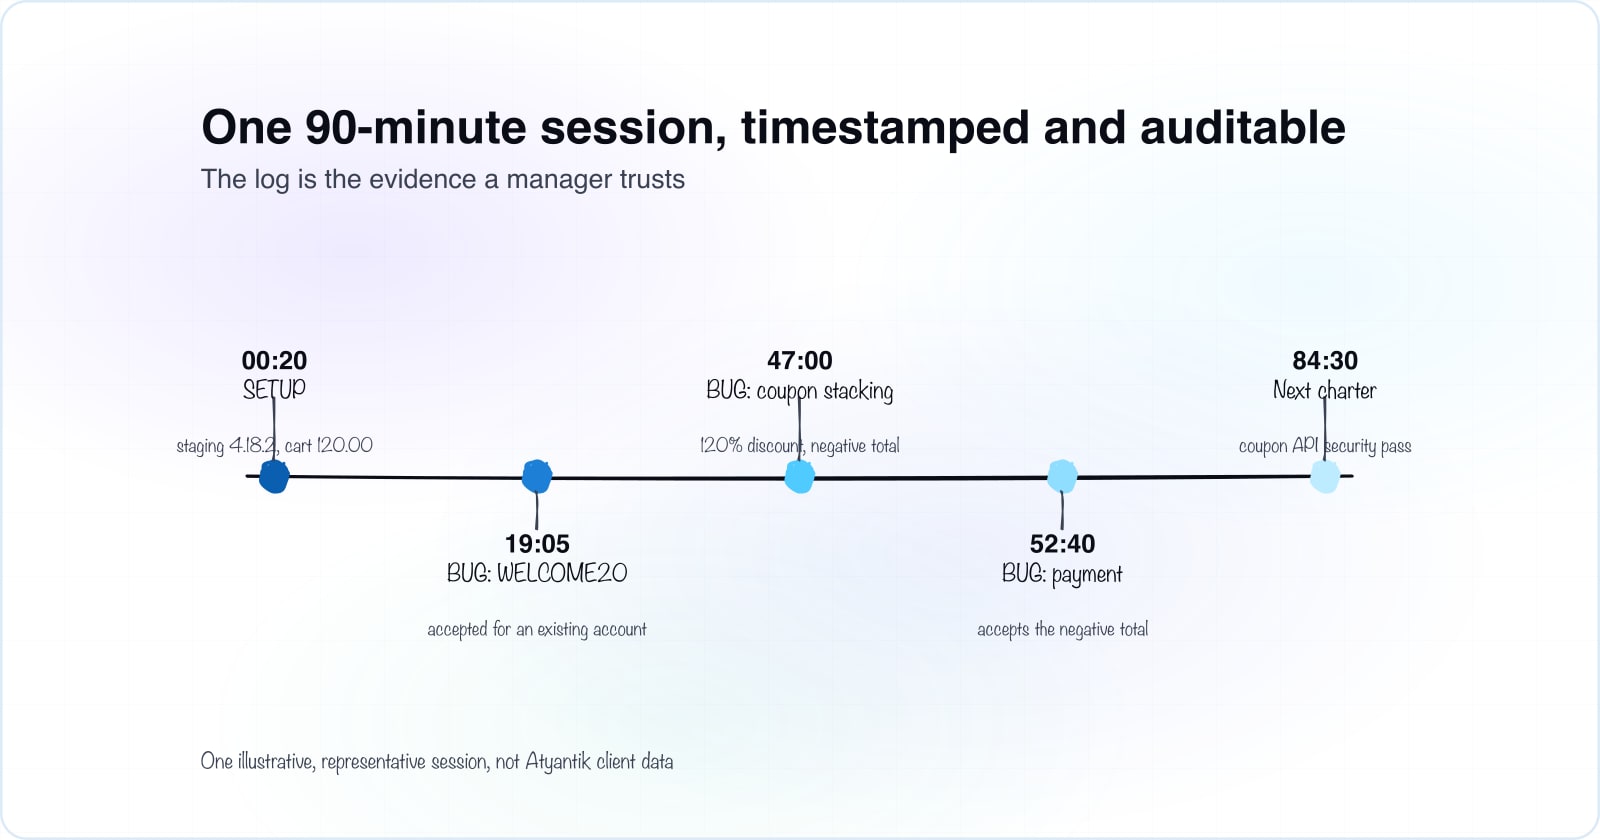
Notice what the timestamps buy you. Because every line is pinned in time, the debrief can point to the exact moment a defect surfaced. For example, at 47:00 the note reads "stacking two coupons yields a 120% discount, a negative order total". That single row is the difference between a claim and a receipt.
The exported session report a manager can grep#
The export is the point. Rapid Reporter writes each note to a CSV row with its sequence, its elapsed timestamp, its type, and its text. Because the format is plain, the artifact is indexable, greppable, and auditable long after the session closes. Here is the raw sheet the session produced.
seq,elapsed,type,note
1,00:20,SETUP,"Env is staging build 4.18.2, seeded catalog, account checkout_qa@example.test"
2,01:10,SETUP,"Coupons on file: SAVE10, FLAT15, FREESHIP, WELCOME20 (new-customer), BULK5 (per-item)"
3,02:40,SETUP,"Cart baseline is 3 items, subtotal 120.00, standard shipping 8.00"
4,04:15,SETUP,"Oracle is the pricing-rules doc v3 plus the coupon admin config"
5,05:30,SETUP,"DevTools network open on /cart/apply-coupon to watch each response"
6,07:05,TEST,"Apply SAVE10 to 120.00, expect 12.00 off"
7,08:12,CHECK,"Total is 116.00 including 8.00 shipping, matches the rules doc"
8,09:40,TEST,"Remove SAVE10, expect the total back to 128.00"
9,11:15,TEST,"Apply FLAT15, expect a flat 15 off the order"
10,12:00,CHECK,"Total is 113.00, correct"
11,14:30,TEST,"Apply EXPIRED1, expect a rejection"
12,15:10,CHECK,"Rejected with ""coupon has expired"", a clear message"
13,17:20,TEST,"Apply WELCOME20 on an existing account, expect a new-customer rejection"
14,19:05,BUG,"WELCOME20 accepted for an existing account; the new-customer gate is not enforced"
15,21:00,TEST,"Enter lowercase save10, expect the same result as SAVE10"
16,21:50,CHECK,"Accepted, 12.00 off, case-insensitive as intended"
17,23:30,TEST,"Enter a code with surrounding spaces, expect a trim and accept"
18,25:10,BUG,"Surrounding spaces are rejected as an invalid code; the input is not trimmed"
19,26:40,QUESTION,"Should codes be trimmed on paste, or is an exact match intended?"
20,29:15,TEST,"Apply SAVE10 then FLAT15, expect the single-coupon rule to block the second"
21,31:40,BUG,"SAVE10 and FLAT15 both apply; the rules doc says one coupon per order"
22,34:05,TEST,"Apply BULK5 per-item across 3 items, expect 15 off"
23,35:30,CHECK,"15.00 off, the per-item math is correct"
24,38:10,TEST,"Change the quantity after a coupon is applied, expect a recalculation"
25,40:25,BUG,"The discount is not recalculated after a quantity change; a stale 15.00 is held"
26,44:30,TEST,"Stack two percentage coupons on a high-value cart, expect a block"
27,47:00,BUG,"Stacking two coupons yields a 120% discount, a negative order total, and checkout stays enabled"
28,50:15,TEST,"Proceed to the test gateway with the negative total"
29,52:40,BUG,"Payment accepts the negative total, amount due is 0.00, and the order is creatable"
30,55:30,TEST,"Apply FREESHIP, expect shipping 0.00"
31,56:20,CHECK,"Shipping zeroed, subtotal unchanged, correct"
32,58:40,TEST,"Apply FREESHIP with SAVE10, expect free shipping and 10% off goods"
33,61:15,TEST,"Apply a coupon on an already-reduced sale item, expect a precedence rule"
34,63:30,BUG,"The coupon stacks on the sale price with no precedence; a double discount results"
35,66:10,TEST,"Apply a coupon, abandon, return to the cart, expect defined persistence"
36,68:00,QUESTION,"Is an applied coupon meant to survive a session timeout?"
37,71:20,TEST,"Submit a 300-character code, expect a graceful rejection"
38,74:30,TEST,"Apply a coupon through the API, bypassing form validation"
39,77:30,QUESTION,"Can the API apply a coupon the form would reject?"
40,80:10,QUESTION,"Should the payment step floor the order total at zero before authorization?"
41,84:30,NEXT-TIME,"Dedicated security charter for coupon API auth and rate limiting"
42,87:40,NEXT-TIME,"Regression charter for the negative-total and stacking defects once fixes land"
The accountability comes from this trail, not from a script. A reviewer can filter the type column to read every BUG in seconds. Furthermore they can jump to 47:00 and see the state that produced the worst defect. In short, the CSV is the object that converts unscripted testing into an auditable record.
What exploratory testing session-based test management proves: coverage and metrics#
A sheet is only useful if it rolls up. Because every note is typed and timestamped, the rollup is arithmetic, not opinion. The session logged 42 notes across the six types. Moreover it produced 7 filed bugs and 4 open questions, and those questions became 2 charters for the next session.
Counted from the session log in this post.
Counted from the session log in this post.
Counted from the session log in this post.
Counted from the session log in this post.
The time split matters as much as the note count. Session-based test management reports time in three buckets: Test, Bug, and Setup. Applying that breakdown to the 90 minutes gives a clear shape. In addition, the on-charter versus on-opportunity split ran roughly 80/20, so most of the time served the stated mission.
Show data table
| Segment | Value (min) | Share |
|---|---|---|
| Test design and execution | 55 | 61.1% |
| Bug investigation and reporting | 27 | 30% |
| Setup | 8 | 8.9% |
Test design and execution took 55 minutes (61%), bug investigation took 27 minutes (30%), and setup took 8 minutes (9%). The on-charter versus on-opportunity split ran about 80/20, so the session stayed on mission. These are illustrative figures from one representative session, not a benchmark.
These numbers are the accountability payload. Because they derive from a timestamped log, a manager can trust them without watching the tester work. Contrast this with an equivalent scripted pass. That pass had no case for coupon stacking, so it never exercised the defect at all.
The debrief: turning the sheet into an answer managers trust#
The debrief is a short conversation the sheet makes possible. Session-based test management frames it as PROOF: Past, Results, Obstacles, Outlook, and Feelings. Because the log is the shared reference, the debrief is a walkthrough, not a memory test. Read the five stages in order.
- Past
What we set out to cover
The coupon-code charter across single coupons, stacking, edge codes, quantity changes, and the payment handoff, in 90 minutes.
- Results
What the session found
7 filed bugs from 42 notes, the worst a coupon-stacking defect at 47:00 that drove a negative order total through checkout.
- Obstacles
What slowed the session
Bug investigation took 30% of the time, and the pricing-rules doc left coupon precedence and trimming undefined.
- Outlook
What comes next
4 open questions became 2 charters: a security pass on the coupon API, and a regression pass once the stacking fixes land.
- Feelings
The tester risk read
Confidence is low on discount math and high on the happy path; the recommendation is a fix-and-regress cycle before release.
That walkthrough is where exploratory testing session-based test management earns the word accountable. Consider the exchange a debrief actually produces.
When to explore and when to automate, the honest limit#
A session is not a regression net, and it is not a substitute for automated tests. It complements automated regression; it never replaces it. Because the two answer different questions, the honest move is to name which one a situation calls for. The matrix below scores that decision across five factors.
| Factor | Run an exploratory session | Write a scripted or automated test |
|---|---|---|
| Feature maturity | Run an exploratory sessionNew or fast-changing behavior nobody has mapped yet | Write a scripted or automated testStable behavior whose rules are already settled |
| Requirement stability | Run an exploratory sessionAmbiguous or partial spec that the session helps clarify | Write a scripted or automated testA firm, agreed spec you can assert against |
| Repeatability need | Run an exploratory sessionA one-off risk hunt across an unpredictable surface | Write a scripted or automated testA check that must run identically on every build |
| Risk profile | Run an exploratory sessionUnknown-unknowns, where the value is discovery | Write a scripted or automated testKnown regressions you cannot afford to reintroduce |
| Oracle clarity | Run an exploratory sessionA judgment call a human has to make in the moment | Write a scripted or automated testA machine-checkable expected result |
Use the two together, in sequence. First a session finds the defect nobody scripted, as the coupon-stacking bug showed. Then the durable ones become automated checks so they never return. The same instinct governs structured accessibility testing sessions, where a charter drives an exploratory pass before automated audits, and it shows up again in the testing techniques used in safety-critical automotive software.
Authoritative sources#
This method and this tool both have primary sources worth reading. Rapid Reporter is Shmuel Gershon's free note-taker for exploratory sessions, documented on his Rapid Reporter project page. Session-based test management was defined by Jonathan and James Bach in the original SBTM paper. For the wider practice, see James Bach on exploratory testing and Cem Kaner's exploratory testing reference. Read them for the theory; use the session above for the practice.